


Training AI models involves processing data. In so-called pre-training, a practically unlimited amount of data is processed. That is why AI training is in the focus of data protection authorities and controllers. Courts, too, will have to assess this question.
Introduction
The lawfulness of AI training is currently being hotly debated. AI is increasingly dominating our everyday lives. For electronic AI models to be powerful, they need as many examples as possible to learn from. These examples are called training data. The volume of training data is so large that a manual review seems impossible.
The Regional Court of Hamburg is currently dealing with a tricky legal question raised by the photographer Robert Kneschke. It concerns the lawfulness of training an AI image model with image data that the German association LAION scraped from the internet. Among other things, this included the photographer's images, and he does not agree with that. LAION image data is embedded in numerous AI image models (Stable Diffusion etc.), which says nothing about their lawfulness. That case is essentially about copyright. However, the GDPR also generally plays a role (people in photos, personal data in texts, etc.).
No powerful AI language model can be expected to come out of Europe.
The lawful mass data simply does not exist.
The USA has this mass data and, on top of that, uses it unlawfully.
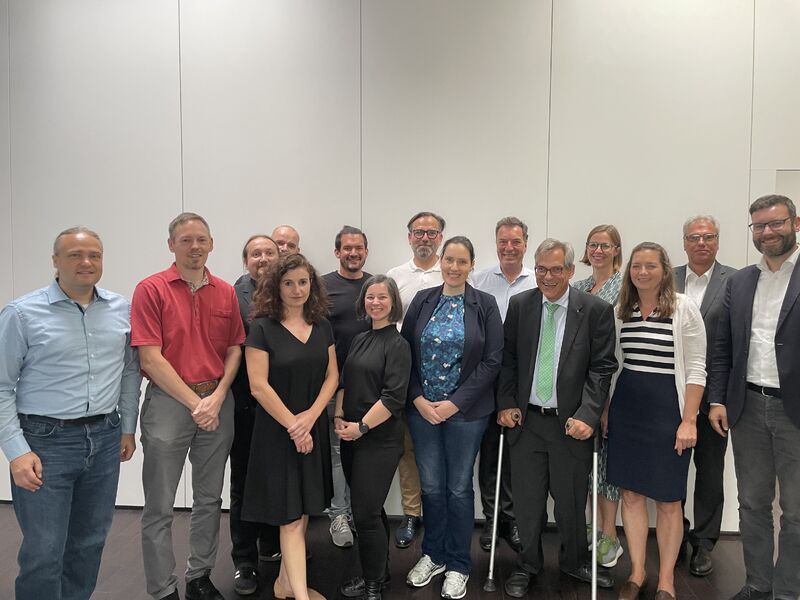
Given the topicality and explosiveness of the subject, the State Commissioner for Data Protection of Lower Saxony (LfD Niedersachsen), Mr Dennis Lehmkemper, has set up an AI expert group. The group meets several times for consultations. The author of this article is a member of this expert group, which discusses questions on AI and data protection in in-person sessions.
The first session took place in Hanover in August. The photo shows the participants.
The Lower Saxony data protection authority collects the findings from the meetings of the AI expert group and will formulate a result from them. The authority gathers interim results of the deliberations and takes them into account for the final result.
The information presented here is solely that of the author and is independent of the opinions of third parties. Nor does it reflect any interim results; it is entirely detached from the discussions of the AI expert group.
The question of what AI training is can be answered briefly as follows:
In pre-training, an AI model is created by being trained with training data. The model can then be used generally and delivers good or very good results for questions that were sufficiently covered in the training data.
In fine-tuning (post-training), an existing AI model is sent off to be educated and specialised. It can then answer questions on a specific subject particularly well. The results are often significantly better than what would be possible with ChatGPT! According to benchmarks, ChatGPT is currently the best language model. But it is a generalist, not a specialist.
Pure prompt tuning, or adding background information to a prompt (RAG), is not training. However, data protection questions arise here as well, but they are not to be discussed here.
Lawfulness of AI training
The lawfulness of AI training depends in particular on the training data. However, the place (the sphere) of the data processing also plays a role.
Training data
Fine-tuning, viewed in isolation, is easier to assess than pre-training. This is because fine-tuning often requires only very little data. Since specialised data is fed in, it is typically also hand-picked. This often gives a very good opportunity for data control.
Anyone who can control all the data can also see more easily whether any of it might be legally problematic.
Data is problematic above all if it constitutes works protected by copyright or if it contains personal data. But data for which confidentiality has been agreed is problematic as well.
Fine-tuning is based on an AI model that has already gone through pre-training. Because fine-tuning thereby also makes use of the training data of the pre-training, these far more extensive training data must also be taken into account in fine-tuning.
Pre-training, by contrast, i.e. building an AI model from scratch, requires so much data that reviewing all of it seems impossible. The amount of data needed for a modern, competitive LLM starts at several billion documents of text. The more data is used for AI training, the better the language model can be. Even though only language models are discussed here, what is said can also be applied to image models or other AI models.
All of this applies above all to generative AI models. A generative model produces creative output. This output draws on parts of the training data and of the prompt (user input). Often the parts that the AI model pulls from its memory come from different documents in the training data. Not infrequently, however, these parts are taken from a single document.
This is how quotations of considerable length come about in AI output. No unlawful privacy attack is needed for this, as the Hamburg Commissioner for Data Protection would like to see it, so that the authority is not responsible for AI of any kind (see the position paper of the Hamburg Commissioner for Data Protection). Another assumption of the Hamburg authority is also wrong: AI language models, and other types of models based on neural networks, potentially store personal data. This can easily be demonstrated (cf. the basic article, easy-to-run prompt experiments or research papers, as well as source code for model training and the resulting model, which can reproduce exact quotations).
 My name is Klaus Meffert. I have a doctorate in computer science and have been working professionally and practically with information technology for over 30 years. I also work as an expert in IT & data protection. I achieve my results by looking at technology and law. This seems absolutely essential to me when it comes to digital data protection. My company, IT Logic GmbH, also offers consulting and development of optimized and secure AI solutions.
