An AI that simply knows all your company documents and can answer any question about them sounds like the perfect solution for every company with accumulated knowledge. Yet there is a surprisingly large gap between that vision and the reality of ChatGPT, Claude and the like. Anyone who understands where generic AI solutions fail with large volumes of company documents makes better decisions for their own digital infrastructure.
Introduction
Imagine a mid-sized company: a machine builder with 150 employees. Over the years it has produced thousands of documents – maintenance logs for every delivered system, technical data sheets, field service reports, internal emails about customer problems, training materials and contracts with suppliers. Altogether that quickly adds up to tens of thousands of files, spread across file servers, an old wiki and countless mailboxes.
Management hears about ChatGPT and Claude and has an obvious idea: why not simply give the AI access to all these documents? Employees could then ask questions like "Which spare parts were replaced most often on system X over the last three years?" or "Show me all open complaints from the last quarter" – and the AI would distil the right answer from the company's entire knowledge.
In theory, that sounds like the perfect use case for generative AI. In practice, it quickly becomes clear that cloud AI services like ChatGPT or Claude are not built for exactly this use case – thousands of your own documents as a reliable basis for answers. The reasons lie in four areas: the limited context length, the ongoing API costs, the necessary foundation of storage and index (RAG), and fundamental limits of this technology for complete or statistical analyses. This article goes through each of these points with concrete examples – and shows why, in the end, an application built specifically for your own use case is often the more practical path.
The context window: a hard limit
Language models like ChatGPT or Claude process text in what is called a context window – a limited "working memory" that must hold all the information of a request: the question itself, the conversation so far and all documents supplied with it.
Even very large context windows of 100,000 to 200,000 tokens correspond to roughly 150 to 300 pages of text. That may be enough for individual reports or contracts – but with thousands of documents it is far too little.
To get around this problem, a special AI database is built that makes your knowledge efficiently usable. You can read more about this topic here (in German).
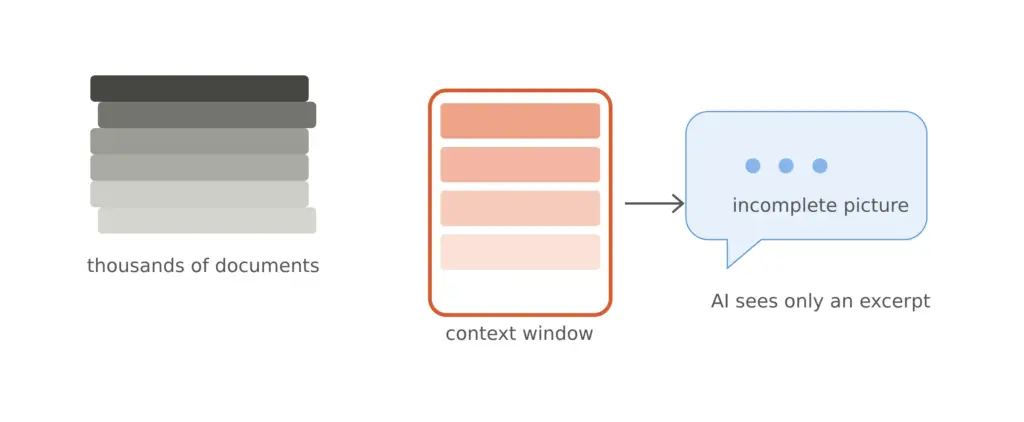
Example: The machine builder from our example has over 3,000 maintenance logs alone, each about two to three pages long. That is already more than 6,000 pages – around twenty times a large context window, for this one document category only. Add data sheets, emails and service reports and you quickly reach tens of thousands of pages. This volume cannot fit into a context window at the same time under any circumstances, no matter how cleverly you shorten or summarise the texts.
This challenge is made worse by the limited capabilities of generative AI. To understand the risks, it is important to know that ChatGPT can give wrong answers.
There is also a more subtle problem: models do not treat every part of a long context equally well. Information that sits "in the middle" of a very long prompt is overlooked or weighted worse more often than information at the beginning or end. Even if you managed to squeeze all relevant documents in somehow, answer quality would suffer – individual important details could get lost in the "noise" of the mass.
This is also why an LLM should not be asked: "How many contracts do we actually have with company XY?" The LLM does not know all your documents. Instead, the documents are pre-selected in an AI preliminary stage via a vector database, and only a few of them are used for the AI's answer. For a counting question to be answered correctly, a suitable AI system (not the same as an AI model!) has to be built that supports this kind of question.
API costs: you pay per token, anew with every request
Cloud AI providers charge per token – both for input (everything you send to the model) and for output (the generated answer). The problem: with every new request, the relevant context has to be sent again, because the model has no memory between two requests.
Example: Suppose that with every request you want to send at least the 20 most relevant document excerpts to enable a well-founded answer – roughly 15,000 to 20,000 tokens of context per request. With 150 employees making an average of five requests per working day, that adds up to around 750 requests a day. The input context alone then totals more than ten million tokens per day – day after day, month after month. Depending on model and provider, this results in ongoing costs of several hundred to over a thousand euros per month, just for repeatedly sending context – without any "new intelligence" being created, merely the same background being processed over and over.
These costs scale linearly with usage. The more successful and popular such a system becomes in the company, the more expensive it gets – an economic model that can quickly spiral out of control if it is not thought through from the start.
Storage, index and RAG: the invisible foundation
To make large volumes of documents usable at all, you need a technical foundation that cloud AI does not bring along itself: Retrieval-Augmented Generation, or RAG for short.
The principle: documents are split into smaller sections (chunks), converted into numerical vectors by an embedding model and stored in a vector database. For a request, the system first searches for the thematically best-matching chunks – only these few sections are then sent to the language model together with the question.
Example: The 6,000 pages of maintenance logs from our example would be split into sections of about 500 words each – resulting in several thousand chunks for this document category alone. Each of these chunks has to be converted into a vector once, which incurs embedding costs. For updates – new maintenance logs keep arriving – this process repeats continuously. In addition, a vector database has to be operated that stores these thousands of vectors and can search them in milliseconds for every request. This is not a one-off setup but permanent infrastructure with its own hosting and maintenance costs – including updates whenever documents change, are deleted or are newly added.
RAG solves a lot – but not everything
RAG is the technical basis that allows cloud AI to handle large volumes of documents in the first place. But RAG has structural limits that cannot simply be "optimised away".
Incomplete retrieval of relevant information. Semantic search returns the chunks that appear most similar to a request – which is not the same as "all relevant information".
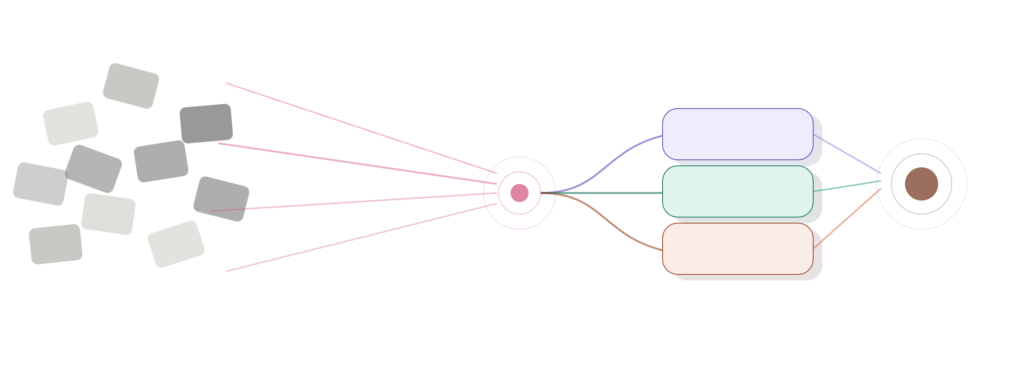
Example: An employee asks: "What problems have we had so far with the HV-200 hydraulic valve?" If this valve is mentioned in 40 different maintenance logs over several years, but the RAG system by default returns only the five to ten most similar hits, the AI sees only a fraction of the relevant reports. The answer might rest on the "loudest" or most recently indexed cases, while older or differently worded problems simply fall by the wayside – without the user noticing that the answer is incomplete.
The quality of the AI's answer therefore depends heavily on the quality of the retrieval mechanism, that is, on how well finding relevant information in (perfect) company knowledge works.
No aggregation and no statistics. By the way it works, RAG cannot answer questions that require an analysis across the entire set of documents.
Example: The question "How many maintenance jobs were there in 2025 in total, and what was the average time spent per job?" cannot be answered reliably with RAG in principle. Semantic search finds passages similar in content to the term "maintenance job" – but it cannot completely capture all logs created in 2025, count them and add up or average their time entries. Even if the AI outputs a number, it is at best based on a small, random sample of the documents found – and in the worst case simply wrong, without this being recognisable.
Why map-reduce is usually not a practical alternative
A theoretical solution for "questions across all documents" is a map-reduce approach: each document is processed individually by the AI, and the partial answers are then merged.
Example: To answer the question about the maintenance logs created in 2025 correctly, you would theoretically have to send each of the several thousand logs individually to the AI, asking it to extract the date and time spent – and then add up the results. With 3,000 documents, that means 3,000 individual API calls for a single user question. Even at a low cost per call, this quickly adds up to double-digit euro amounts – for a question a human could have asked in two seconds if the data had been in a table. In terms of time, processing takes several minutes even with parallelisation, which is unacceptable for an interactive chat application. Anyone who relies on their own hardware instead to save costs faces a similar dilemma: buying powerful graphics cards for occasional batch processing is hard to justify economically.
Structured data storage as a complement – with an important caveat
An obvious approach: instead of leaving everything to the AI, relevant information is extracted once when the documents are ingested and stored in a structured way in a classic database such as PostgreSQL. Aggregation questions then run through normal database queries – fast, reliable and without ongoing AI costs.
Example: For each maintenance log, fields such as system ID, date, replaced parts and time spent could be written to a table automatically on import. The question about the average effort in 2025 would then be a simple SQL query that returns an exact result in milliseconds – without any AI call at runtime.
The caveat: structured data storage requires a schema – that is, defined fields and data types. But this schema follows from the respective use case. Invoices call for different information than contracts, support tickets or maintenance logs. Without knowing which questions will be asked later, it is hard to decide which fields should be extracted at all.
Nevertheless, a generic base layer can be built: a full-text search across all documents, general metadata such as date, file type or source, and a vector index for semantic search. That covers basic search and research questions – but domain-specific analyses like those in the maintenance log example remain out of reach.
The consequence: purpose-built, specialised applications
At this point it becomes clear why generic "AI on all company data" solutions disappoint in practice, and why a specially developed application is often worthwhile.
A purpose-built application knows the domain: it knows which document types occur, which fields are relevant and how documents relate to each other. For the machine builder in our example, that would concretely mean: maintenance logs are captured in a structured way (system, date, parts, time spent), while training materials or general emails are made accessible mainly through full-text and semantic search. On this basis, a schema can be designed that sensibly combines both structured queries (counts, statistics, filters) and semantic search (RAG).
A practical path is often two-stage: first, a generic base layer of full-text and vector search is built, which already answers many questions. Then you observe which types of questions actually come up in practice – and add structured extensions specifically for the most important and most frequent ones, instead of trying to anticipate every conceivable use case up front.
In such a system, AI is used at precisely defined points: for the one-off extraction and indexing of documents, for semantic search at runtime, and for phrasing understandable answers based on database results and retrieved text passages. The expensive and unreliable idea that an AI could "simply read and understand everything" is dropped – in favour of a system that actually works for the respective use case.
Conclusion
Cloud AI services like ChatGPT or Claude are excellent tools for individual documents, short research tasks or for phrasing answers. As a direct basis for comprehensive company knowledge with thousands of documents, however, they are unsuitable – limited by the context window, driven by linearly growing API costs and fundamentally unable to deliver reliable aggregations or statistics over large amounts of data.
RAG is a necessary but not a sufficient building block. Anyone who wants truly robust, company-wide answers – including counts, analyses and full coverage of relevant documents – can hardly avoid a well-thought-out application tailored to their own use case. The good news: with open technologies, such a system can be built incrementally, without depending on individual cloud providers or their pricing models.
All articles on offline AI, open language models and company knowledge are collected in the Local AI overview.
 My name is Klaus Meffert. I have a doctorate in computer science and have been working professionally and practically with information technology for over 30 years. I also work as an expert in IT & data protection. I achieve my results by looking at technology and law. This seems absolutely essential to me when it comes to digital data protection. My company, IT Logic GmbH, also offers consulting and development of optimized and secure AI solutions.